Purpose and motivation
Natural language processing models for truthfulness detection often remain confined to isolated research notebooks. NoKe was designed to bridge that gap by treating fake news detection as a complete software and machine learning engineering problem.
The project implements a reproducible training pipeline, compares tree-based models with fine-tuned transformers on benchmark data, incorporates error interpretability tools, and exposes predictions through both a containerized API and a browser extension.
Dataset and modeling approaches
The system is trained and evaluated on the LIAR-PLUS dataset, a widely studied benchmark containing political claims annotated with six veracity ratings, speaker metadata, historical truthfulness counts, and contextual justification texts.
Two distinct model architectures are implemented:
- Baseline classifier: A Random Forest model built using scikit-learn. Text inputs pass through a custom
TreeFeaturizerthat extracts TF-IDF ngram vectors, credit score bins calculated from speaker truth history (compute_credit_bins.py), and categorical contextual metadata. - Transformer model: A deep learning classifier using
RobertaForSequenceClassificationfrom Hugging Face Transformers. The network is fine-tuned using PyTorch Lightning, which manages training loops, learning rate scheduling, and validation logging.
Pipeline reproducibility and MLOps tooling
The repository uses standard MLOps tools to maintain reproducibility across data preparation and training:
- Dependency management: Managed with
uv, enabling fast, deterministic dependency resolution and environment synchronization. - Data Version Control (DVC): DVC stages define pipeline dependencies and outputs (
dvc.yaml), linking raw data ingestion, preprocessing, credit bin calculations, and model execution so steps run only when source inputs change. - Experiment tracking: MLflow logs training parameters, loss curves, confusion matrices, and validation metrics (F1 score, accuracy, AUC).
- Data validation: Great Expectations runs an automated test suite (
fake_news_data_suite.json) over processed data files to verify schema conformity and prevent data leakage before model training begins. - Continuous integration: GitHub Actions runs pytest test suites covering featurization logic, data loaders, and model interfaces on repository updates.
Model interpretability and deployment
To understand why a statement is flagged, SHAP (Shapley Additive Explanations) is integrated into the error analysis pipeline. SHAP values quantify the contribution of individual words and speaker credit scores toward the final prediction, helping verify that predictions rely on genuine signals rather than dataset artifacts.
The serving infrastructure includes:
- API layer: A FastAPI application exposing a
/api/predict-fakenessendpoint for programmatic inferences. - Containerization: A Dockerfile packaging the FastAPI server, model artifacts, and dependencies into an isolated runtime image.
- Browser integration: A Chrome extension (
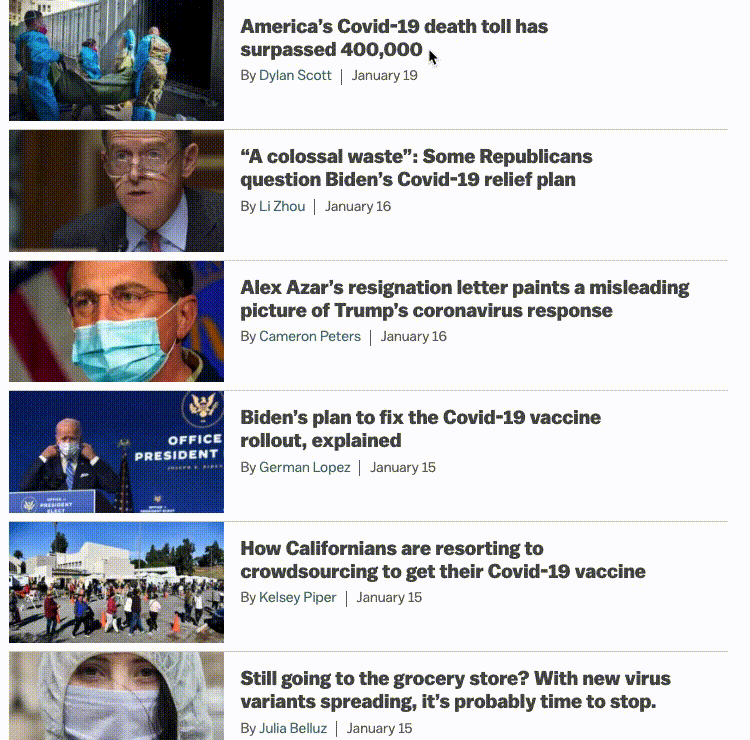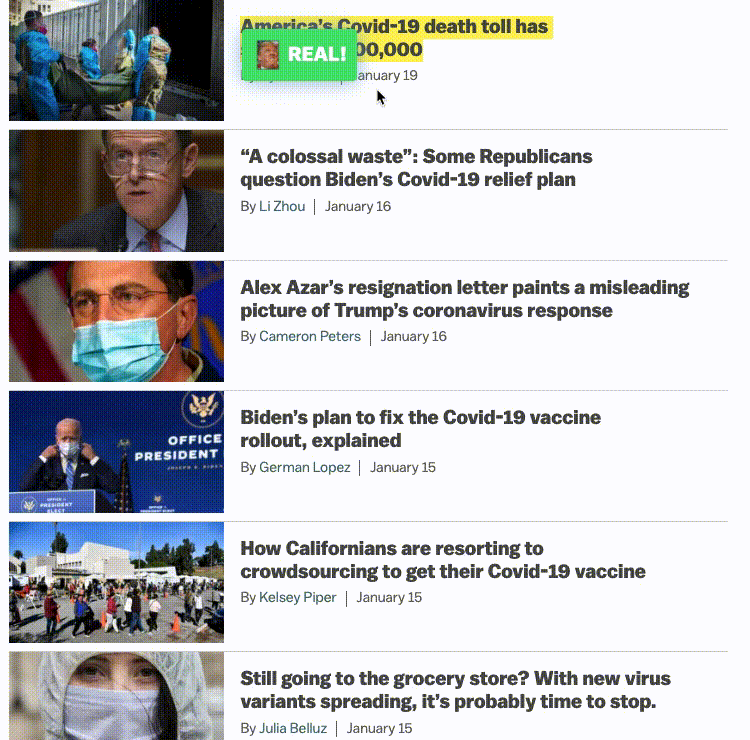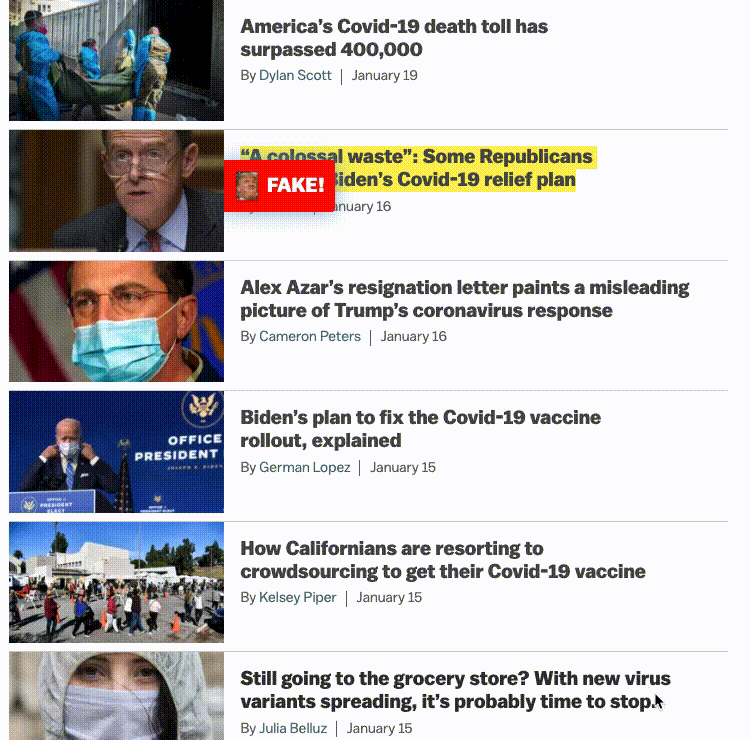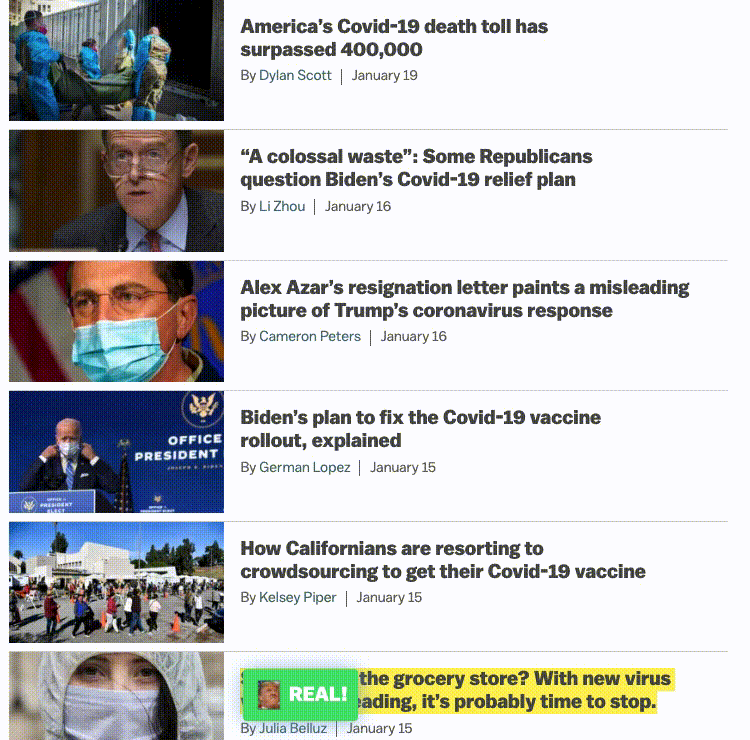
manifest.json,content.js) that lets users select text on web pages and view real-time veracity assessments without leaving their browser.
Here's a (very short) demo!